Know how full the window is
A meter under the composer estimating how much of the model's context this conversation has used, beside a live word, character and sentence count.
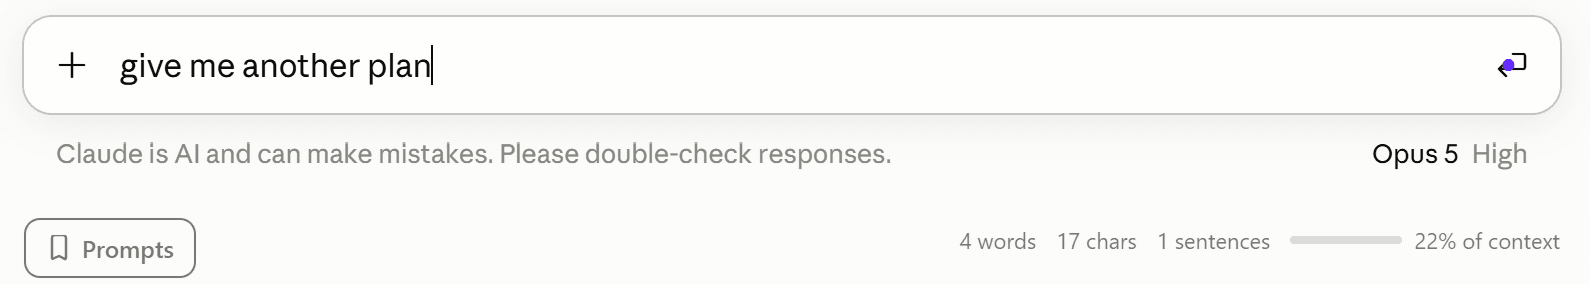
The meter compares the stored size of the conversation against the context window of the model it is using, read from each platform's own API, with a conservative fallback for a model it doesn't recognise. It is an estimate and the interface labels it as one.
Both readouts update as you type, through a passive listener that never wraps the page's own handlers. The bar turns amber and then red as you approach the limit, so starting a fresh thread becomes a decision you make rather than one you stumble into.
Both readouts are free, on ChatGPT and Claude. The token figure is an approximation — good for telling 20% from 90%, not for exact accounting. Sentence counting handles Arabic and CJK terminators, not only the Latin full stop.
Long conversations degrade in a way that's hard to see coming. The model starts losing details from earlier in the thread, and the only signal you get is that the answers quietly get worse. Neither Claude nor ChatGPT shows you how full the context window is. ChatPeer adds a meter under the composer that estimates how much of the window the current conversation has consumed, turning amber and then red as you approach the limit, so starting a fresh thread becomes a decision you make deliberately rather than a fix you stumble onto. Beside it sits a live count of the words, characters, and sentences in what you're currently typing — useful when you're drafting something to a length, and honest about non-English text in a way naive counters aren't.
How the estimate is produced
The meter multiplies the stored size of the conversation by a characters-per-token heuristic and compares it to the context window of the model that conversation is using. ChatPeer reads the model from each platform's own API — Claude reports it in the conversation list, ChatGPT in the conversation detail — and falls back to a conservative default when the model isn't recognised, so a newly released model under-promises rather than overstating the room you have. It is an estimate, and the interface labels it as one: a real tokeniser would mean shipping megabytes of model-specific vocabulary into the page, and would still be wrong the day a platform switched models.
Counting words in any language
The counter splits on punctuation as well as whitespace, and recognises sentence terminators beyond the Latin full stop — including the Arabic question mark and the Urdu full stop, which are distinct characters from their English counterparts. A counter that only knows about '.', '!' and '?' reports one enormous sentence for an entire Arabic paragraph. This one doesn't.
Live updates without touching the page
Both readouts update as you type. ChatPeer reads the composer's contents through a passive listener and never wraps, patches, or intercepts the page's own event handlers — a hard rule in the extension, because breaking the host page is worse than any feature is good. The meter's stored figure is fetched once per conversation and cached rather than recalculated on every keystroke.
Both readouts are free
The context meter and the word counter are available on the free tier on both Claude and ChatGPT. There's no upsell attached to knowing how full your context window is.
Questions about this feature
It's an approximation based on character counts, and the interface labels it as approximate. It's reliable enough to tell you whether you're at roughly 20% or roughly 90% of the window, which is the decision it exists to support.
It recognises the current Claude and ChatGPT model families and falls back to a conservative default for anything unfamiliar, so an unrecognised model shows less headroom rather than more.
Yes. Sentence detection includes Arabic and CJK terminators, and the token estimate accounts for non-Latin scripts being denser per character than English.
Stop scrolling for it
Free to install. No account required.